AI
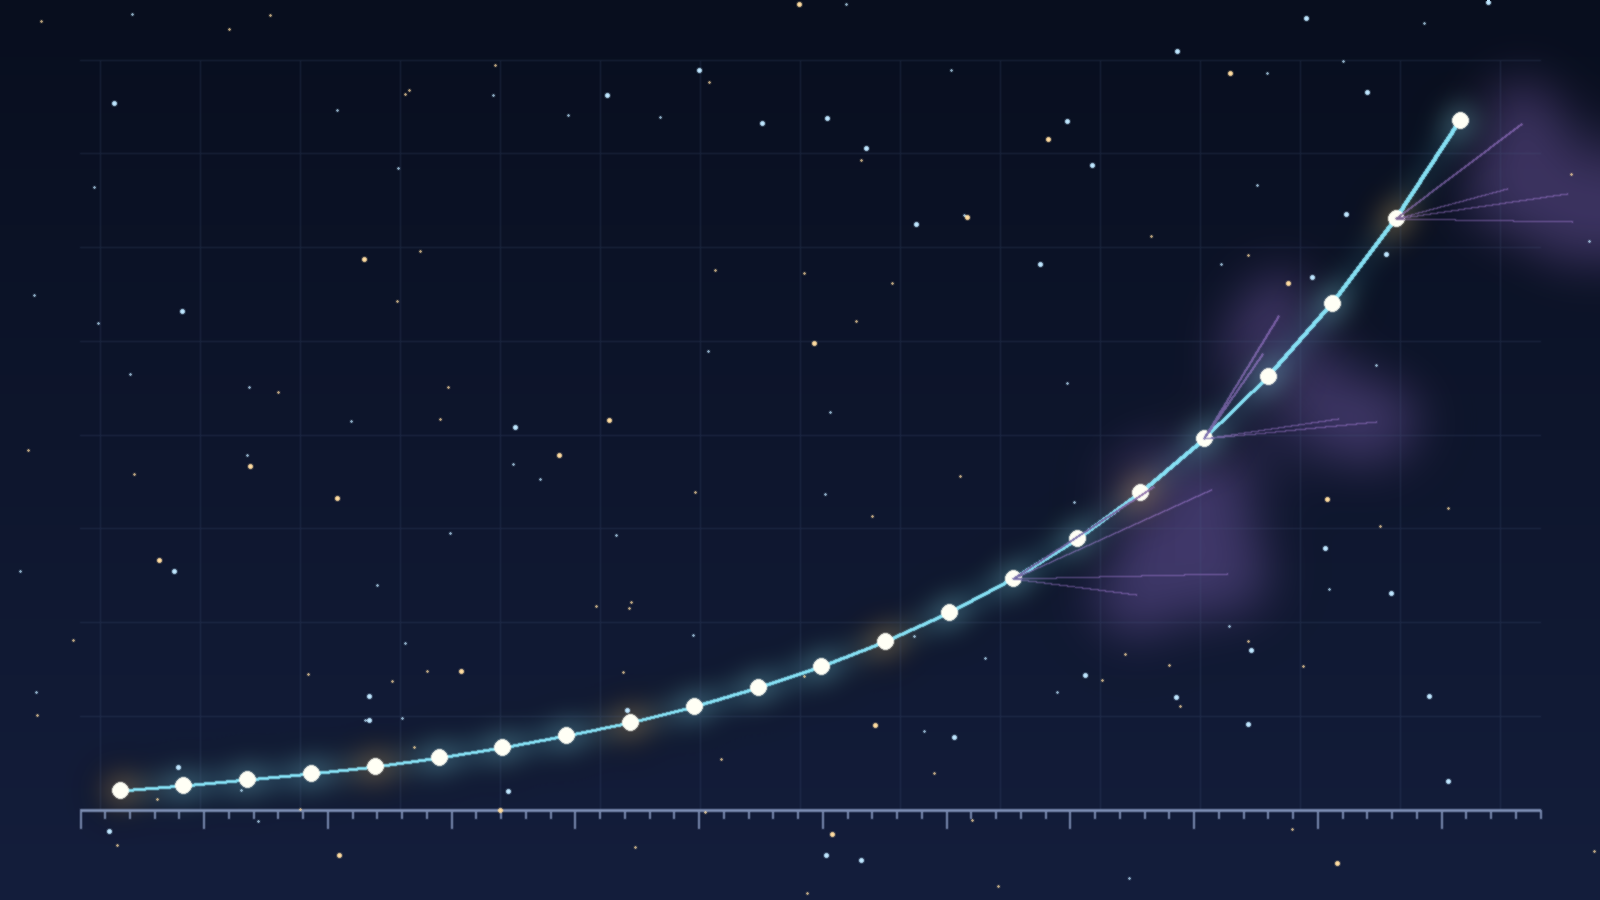
METR Finds AI Time Horizons Still Doubling Every 3.6 Months, but Models Lag Human Experts on Judgment
The AI evaluation nonprofit's latest capability update adds harder, more open-ended tasks to its closely watched time-horizon chart. Frontier agents now usually match or beat skilled humans on coding and optimization work, yet fall short when good results depend on judgment without fast feedback.